Four AI Giants Will Let Websites Block Training With One Line, but It Can't Undo What They Already Scraped
Google, OpenAI, Anthropic and Microsoft committed to honor a single robots.txt signal that lets websites block scraping for generative AI training, though it only stops future crawling and Meta has not committed to implement it.

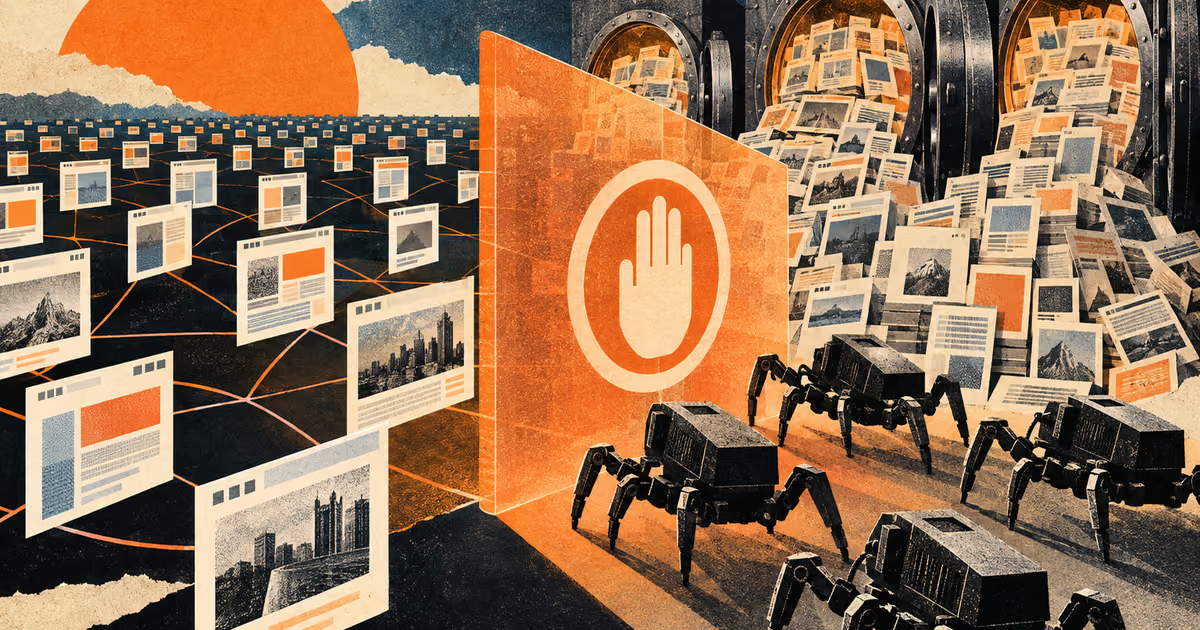
Website owners may soon get a simple way to tell the biggest AI companies to stop taking their pages for training. Google, OpenAI, Anthropic and Microsoft have committed to honor a new robots.txt directive that does the job with a single entry.
The catch is built in. A page that was already crawled stays crawled, and the companies keep what they have. The new signal only stops future scraping, and most of the rollout is still months away.
One rule instead of a crawler hunt
Today, a site owner has to identify each crawler and add a separate rule for each provider. A provider that runs several scrapers needs an entry for every one of them.
The new approach replaces that chase with one common signal, a dedicated user agent for AI training:
User-Agent: __usage_ai-training
Disallow: /
Allow: /press-kit/
The last line is optional. It lets an owner block training across a site while permitting it on specific sections.
The four companies are adopting a proposal under consideration at the IETF, the Internet Engineering Task Force, which maintains the Robots Exclusion Protocol. Kevin Kelley, Anthropic's technical lead for standards, wrote it, and a draft has been submitted. It has not become a standard yet, so for now the force behind it is the companies' own commitment.
What the line does and doesn't block
The directive is narrow. It blocks crawlers gathering AI training data, and it leaves ordinary crawling alone. A site that uses it does not disappear from Google Search.
Google will read the signal as a stop sign for Google-Extended, the user agent that collects material used to train Gemini. The rule also has an exception: it does not apply to models that "perform exclusively non-generative tasks."
Timing varies by company. Anthropic already supports the directive. Microsoft starts on February 1, 2027, and Google plans to follow in early 2027. OpenAI has pledged to implement it in the coming months.
The next fight is over answers
Training is only one reason an AI system fetches a page. Sometimes a model grabs one to answer a user's question on the spot, and the training directive isn't aimed at that.
Microsoft will offer a separate setting for it, called AI Grounding, which lets site operators block those requests. The setting extends to third party AI tools built on Microsoft technology. OpenAI plans similar controls.
The company missing from the list
Meta says it supports the idea but has not committed to implementing it. That gap stands out after the past few weeks. Its new commercial terms, set to take effect October 30, authorize it to crawl websites tied to businesses on Facebook, Instagram, WhatsApp and Messenger and use the content to train its products. Meta has answered critics by saying content owners can still manage access with robots.txt.
So the new line gives publishers a cleaner way to speak to four of the largest AI companies from here on. It can't reach back to what those companies already hold, and the fifth name publishers would want on the list has so far offered only its support.
Some offers on this page may be paid placements or contain affiliate links.
Subscribe to Techpresso
Free daily newsletter, read in 5 minutes.
Subscribe free